27B
General multimodal model
Qwen3.6 27B
Chat, document and image analysis, coding and long-context tasks.
QuantizationGGUF Q4_K_M or Q5_K_Mabout 17–22 GB of weights
ConfigurationOne ASUS GX10 node
ASUS GX10 has 128 GB of memory shared by the CPU and GPU. Account for model weights, context, the operating system and working data within this capacity.
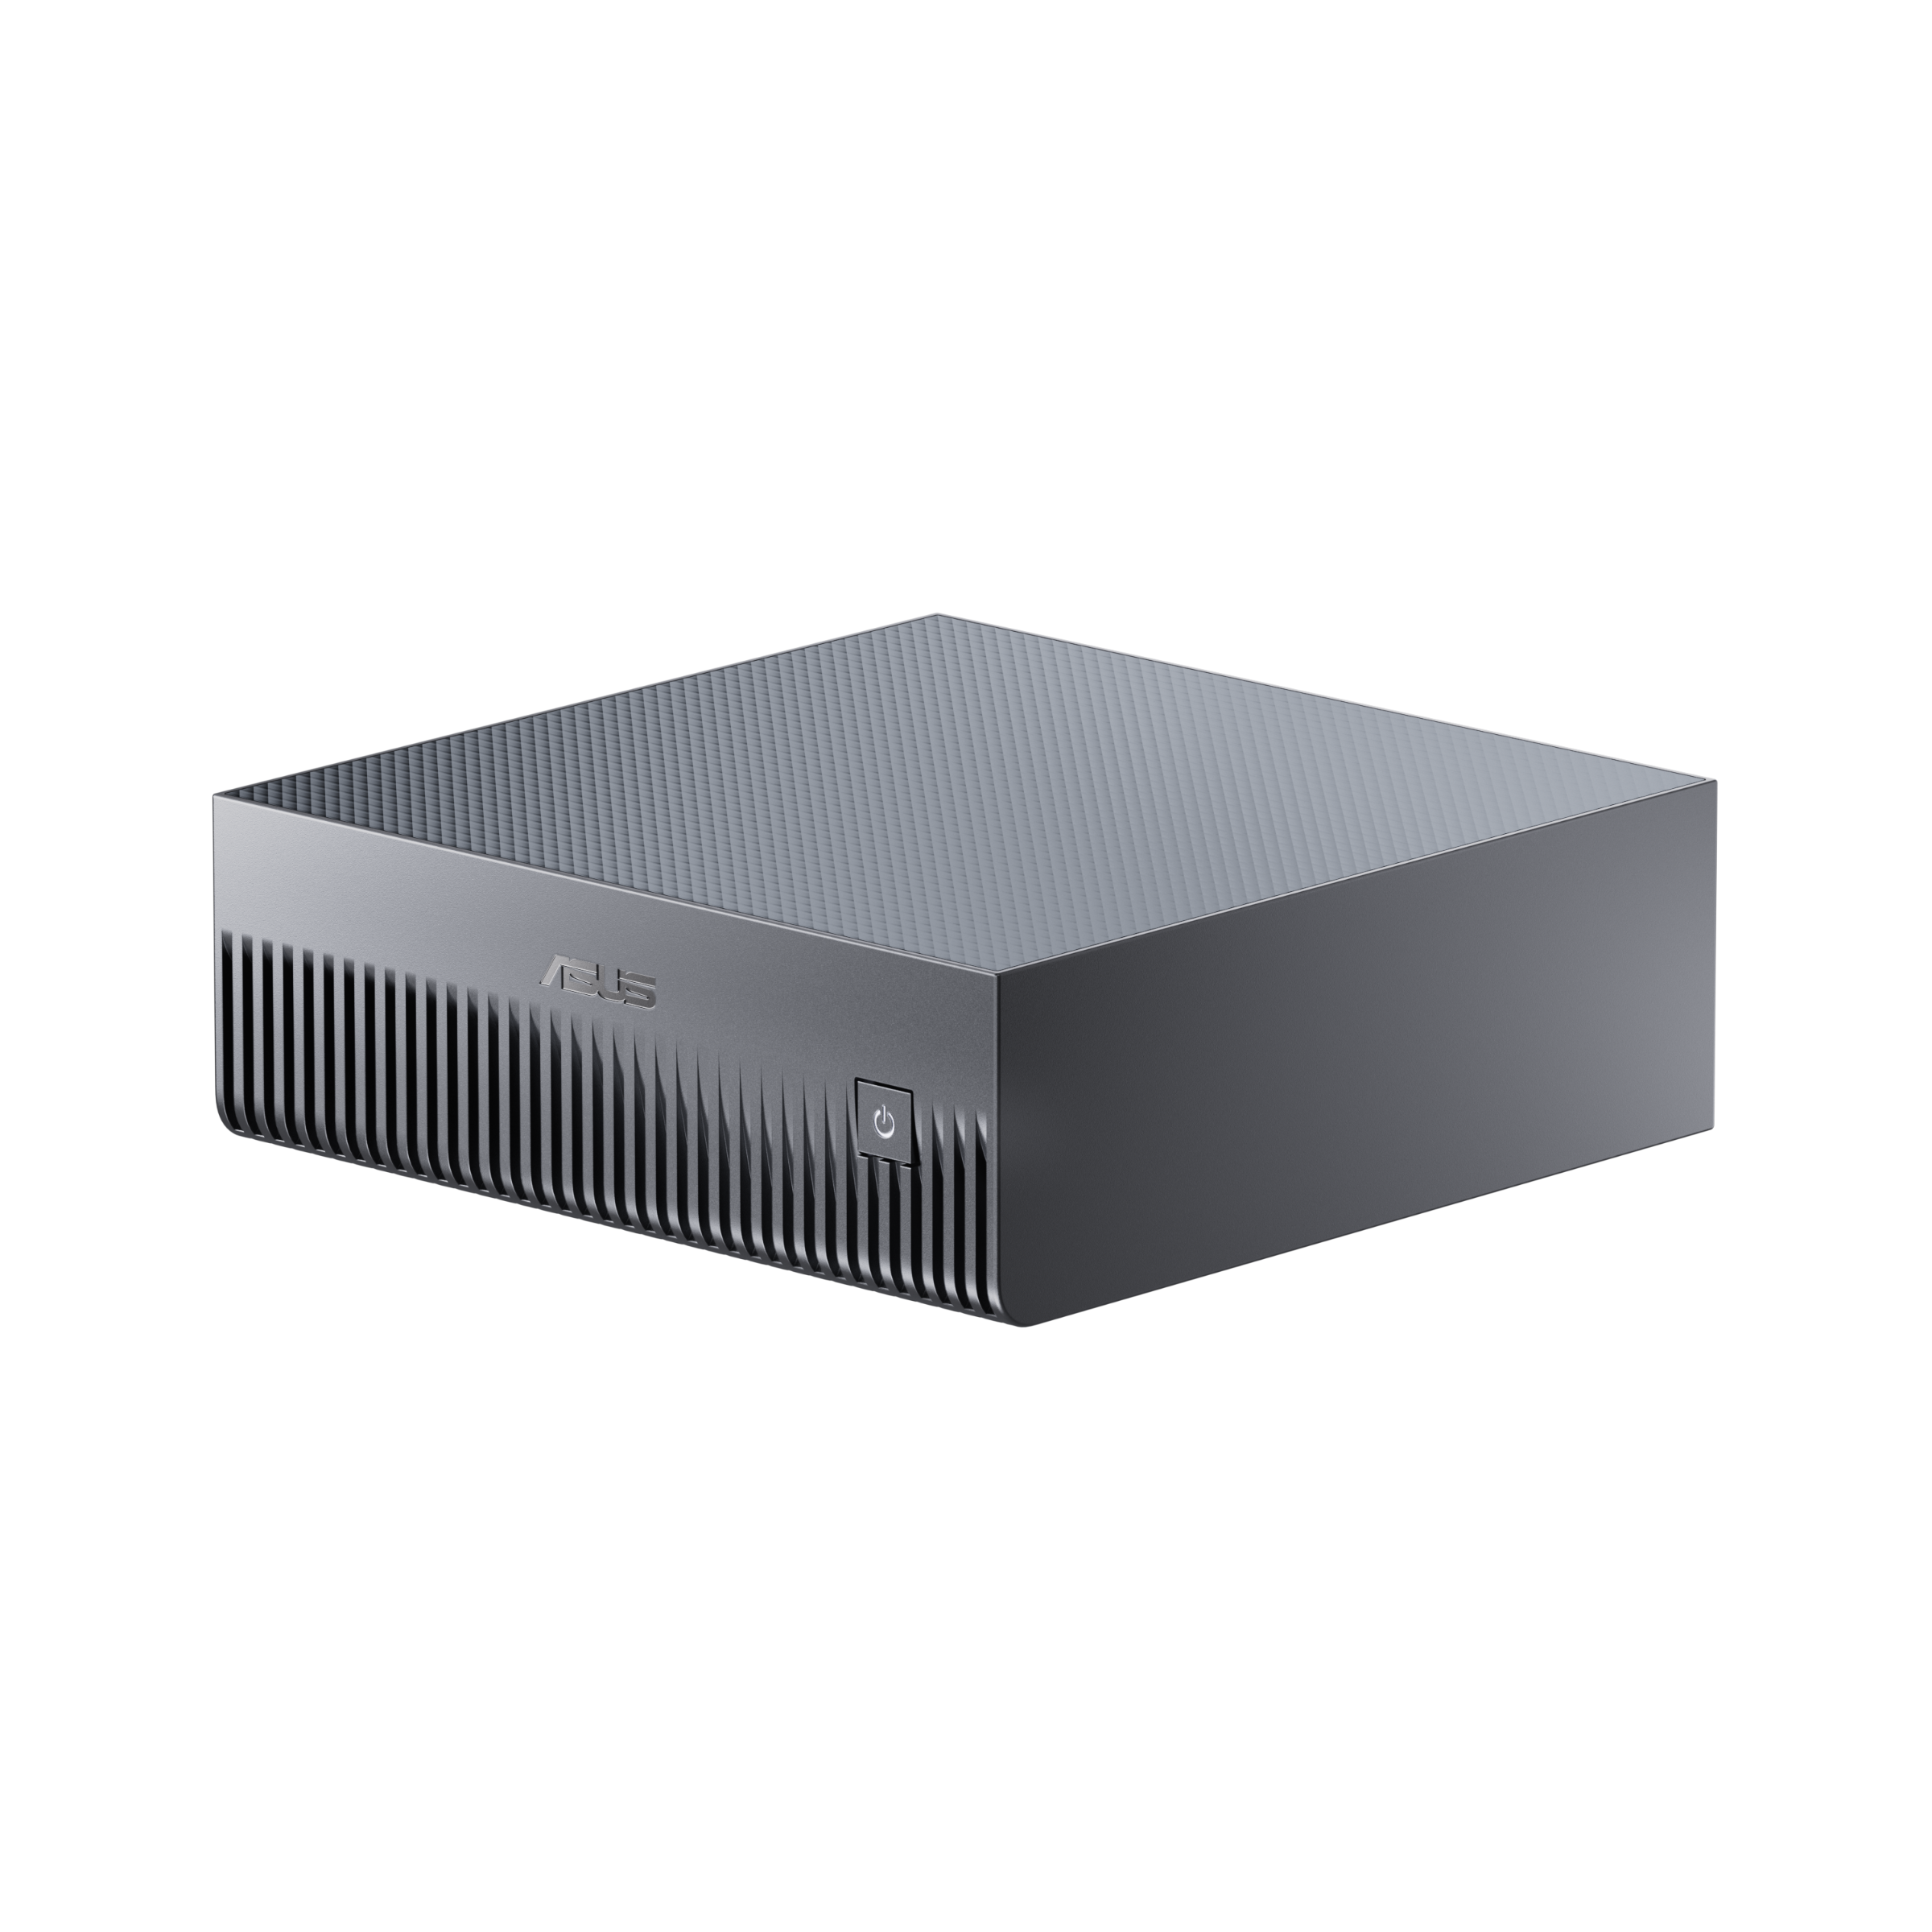
ASUS GX10 with 128 GB of unified memory
128 GB of unified memory for model weights, context and LLM experiments.
The catalog lists workloads, quantizations and weight sizes. Six models are preinstalled on ASUS GX10.
General multimodal model
Chat, document and image analysis, coding and long-context tasks.
Fast MoE model for coding and analysis
For coding, chat and image analysis. The MoE architecture activates only part of its parameters per token.
Code, repositories and agents
A specialist model for codebases, debugging, code generation and tool-using workflows.
Large open model for demanding prompts
OpenAI’s MoE model with native MXFP4 weights for reasoning, coding and local assistant workloads.
Image and video understanding
Answers questions about screenshots, photos, video and visually rich documents.
Chat and writing
Preinstalled on ASUS GX10. Works in English and Russian across writing, translation and document tasks.
Development and coding agents
Preinstalled on ASUS GX10. Writes and explains code, helps debug apps and work with tools.
Reasoning, maths and logic
Preinstalled DeepSeek-R1 distillation based on Qwen 32B for multi-step problems and analysis.
Images and documents
Preinstalled on ASUS GX10. Understands text and images, including screenshots, diagrams and document pages.
Chat and long documents
Preinstalled on ASUS GX10 for detailed answers, summarization and conversational applications.
Uncensored chat and creative writing
Preinstalled uncensored model based on Llama 3.1 for open-ended chat and creative writing.
Image generation and editing
Black Forest Labs open weights for prompt-based image generation and editing an input image.
Image generation and in-image text
Qwen image generation and editing model, including compositions with embedded text.
Video from text or image
One model supports text-to-video generation and animation of an input image.
Text-to-video generation
A larger Wan MoE model for text-to-video. We check the full pipeline and speed for the requested resolution.
Financial news and text
For financial sentiment classification and analysis of news and reports. It does not provide a ready-made trading strategy.
Time-series forecasting
A specialist time-series forecasting model for experiments with historical market data and backtests.
Speech synthesis and voice design
Generates speech from text and supports voice design. We check the selected voice and mode for Russian in advance.
MoE model for chat and code
A large Mistral model for text and coding. It can run quantized on one node or be split across two.
One ASUS Ascent GX10 has 128 GB of LPDDR5x memory shared by the CPU, GPU and operating system. Include model weights, KV cache, context and working data when estimating memory use. The system can run quantized LLM inference, RAG, AI agents and fine-tuning tests when the full workload fits in available memory.
ASUS GX10 uses the NVIDIA GB10 Grace Blackwell platform and an ARM64 CPU. Containers, libraries and CUDA extensions must support this architecture. Share your model, quantization, context length and software versions so we can check compatibility and confirm the rate, availability and rental period.
Compare with NVIDIA DGX SparkOne hourly rate applies to the selected rental duration. The calculator multiplies it by the full rental period.
The rate is for one ASUS Ascent GX10 with 128 GB of memory shared by the CPU and GPU.
The table lists the hourly rate and memory capacity for each configuration.
GX10 uses memory shared by the CPU and GPU. RTX and A100 use dedicated GPU memory.
The “from” rate applies to rentals of 169 hours or more.
The CPU, GPU, operating system and applications share LPDDR5x. The operating system and runtime use part of the memory.
Run independent workloads at the same time or distribute one model when your software supports multi-node execution.
| Configuration | Memory | Per hour |
|---|---|---|
| ASUS Ascent GX10NVIDIA GB10 · Blackwell | 128 GBCPU + GPU | Offer ends in—d—h—m—s |
| 2 × ASUS Ascent GX10NVIDIA GB10 · Blackwell | 2 × 128 GBunified per node | Offer ends in—d—h—m—s |
| RTX 3090 | 24 GBVRAM | $0.40/ hour |
| RTX 4090 | 24 GBVRAM | $0.712/ hour |
| RTX 5090 | 32 GBVRAM | $0.952/ hour |
| A100 SXM 80 GB | 80 GBVRAM | $1.432/ hour |
| H100 SXM 80 GB | 80 GBVRAM | $3.192/ hour |
Run the model and working data on one ASUS GX10 if they fit in available memory. Compare model sizes and quantization formats without setting up a cluster.
Use the memory budget for KV cache, documents in context and application data. Match conversation length and concurrent requests to your service.
Test LoRA or QLoRA on your dataset. Memory for weights, activations and buffers depends on the method, model and batch size.
Estimate model weight memory first. Then add the KV cache, runtime, operating system and working buffers.
| Parameters | 4 bit | 8 bit | 16 bit |
|---|---|---|---|
| 8B | 4 | 8 | 16 |
| 14B | 7 | 14 | 28 |
| 32B | 16 | 32 | 64 |
| 70B | 35 | 70 | 140 |
| 120B | 60 | 120 | 240 |
Calculation: parameter count × bit width / 8. Excludes quantization metadata, context and runtime overhead.
A 24 GB card cannot hold these weights entirely in VRAM, even before adding context. GX10 offers a larger shared 128 GB CPU and GPU memory budget. Context length and concurrent requests also determine the final footprint.
Choose the two-system ASUS GX10 cluster for models that need more than 128 GB or for parallel workloads.
All models for ASUS GX10Each node has 128 GB of memory shared by the CPU and GPU. The system is built on NVIDIA GB10 Grace Blackwell.
ASUS technical specificationsShare your model, weight format, engine, context length and preferred dates. For fine-tuning, include the method and dataset size.
Discuss ARM64 compatibility, access, storage, the final price and availability. A request becomes a rental once the terms are agreed.
Connect using the agreed method and run a small example. Measure memory and speed at your target context length before starting the main workload.
Provide your model, software environment and rental period. We will confirm the rate, availability and connection method before the rental starts.
The current rate appears on this page. Budget for runtime as well as the hourly price: more memory can help a workload fit, but does not determine its speed. The final price, rental duration and resources are agreed on request.
It is LPDDR5x system memory shared by the CPU and GPU, rather than dedicated graphics memory. The OS, runtime and buffers use part of it. Model weights and KV cache must fit together. Its performance is not directly interchangeable with GDDR or HBM on a discrete GPU.
A quantized 70B model may fit, depending on the format, context and engine. FP16/BF16 weights alone need roughly 140 GB, so do not expect a fully memory-resident unquantized 70B model in 128 GB. At 4 bits, the basic weight estimate is about 35 GB, plus metadata, KV cache and runtime. Share the exact model for an assessment.
These tools have GX10 deployment paths, but compatibility depends on the version and build. A Docker image must support linux/arm64; PyTorch, CUDA libraries and the inference engine must support NVIDIA GB10/Blackwell. An x86-64 image may need rebuilding. Share exact versions and any custom CUDA extensions before agreeing on the environment.
We have not yet published our own TPS measurements for the offered GX10. Speed depends on the model, quantization, input length, context, engine and concurrency. Compare time to first token and subsequent generation speed separately using the same workload.
Start with one node if the model, context and working data fit and performance meets your needs. A second node supports parallel jobs or a compatible distributed setup. It does not automatically remove a single process’s memory limits. Both configurations use the same pool of two devices, so their availability is linked.
The offered node is ASUS Ascent GX10, rather than the NVIDIA DGX Spark device. Both are based on NVIDIA GB10 Grace Blackwell and related software; enclosure, cooling and configuration options depend on the manufacturer. DGX OS is NVIDIA’s operating-system name and does not change who makes GX10.
Include the model link, quantization format, engine and container versions, context length and concurrency. For fine-tuning, add the method, batch size and dataset size. Share dates, duration, and access and retention requirements. Prepare a small first-run example; keep secrets and private keys out of the request.
How to account for unified memory, context length and ARM64 compatibility.
CHOOSING A SETUPWhen one node is enough, and when parallel or distributed computing helps.
DOCUMENTATIONMemory, architecture and software compatibility: three things to start with.