Single-GPU inference
Start with a model and context that fit within 24 GB together with runtime overhead.
Ada Lovelace GeForce for CUDA workloads, inference and GPU rendering.
Choosing RTX 4090 to run a language model? Compare your workload with ASUS Ascent GX10 rental: NVIDIA GB10 and 128 GB of unified CPU and GPU memory on one node.
Request one ASUS system for inference and RAG, or a pair for parallel workloads. Compare model and context memory, ARM64 support and the time needed for a trial run. GX10 unified memory and dedicated VRAM have different trade-offs.
RTX 4090 or ASUS GX10 for LLMs128 GB unified memory · NVIDIA GB10 · one system or a pair. Availability and software are agreed for your workload.
Start with a model and context that fit within 24 GB together with runtime overhead.
Test image generation and data processing with a reproducible set of examples.
Compare quality and frame time in a renderer that supports Ada Lovelace.
Provide your model, software environment and rental period. We will confirm the rate, availability and connection method before the rental starts.
The GPU has 24 GB of GDDR6X. Include runtime memory and working buffers in the total.
It depends on the model, sequence length and training method. Specify full fine-tuning or adapters, precision and batch size; the weights file alone does not show training memory requirements.
This configuration is open for rental requests. Share your workload, preferred dates and duration. Hardware availability, pricing and access dates are confirmed individually; a request does not create a confirmed booking.
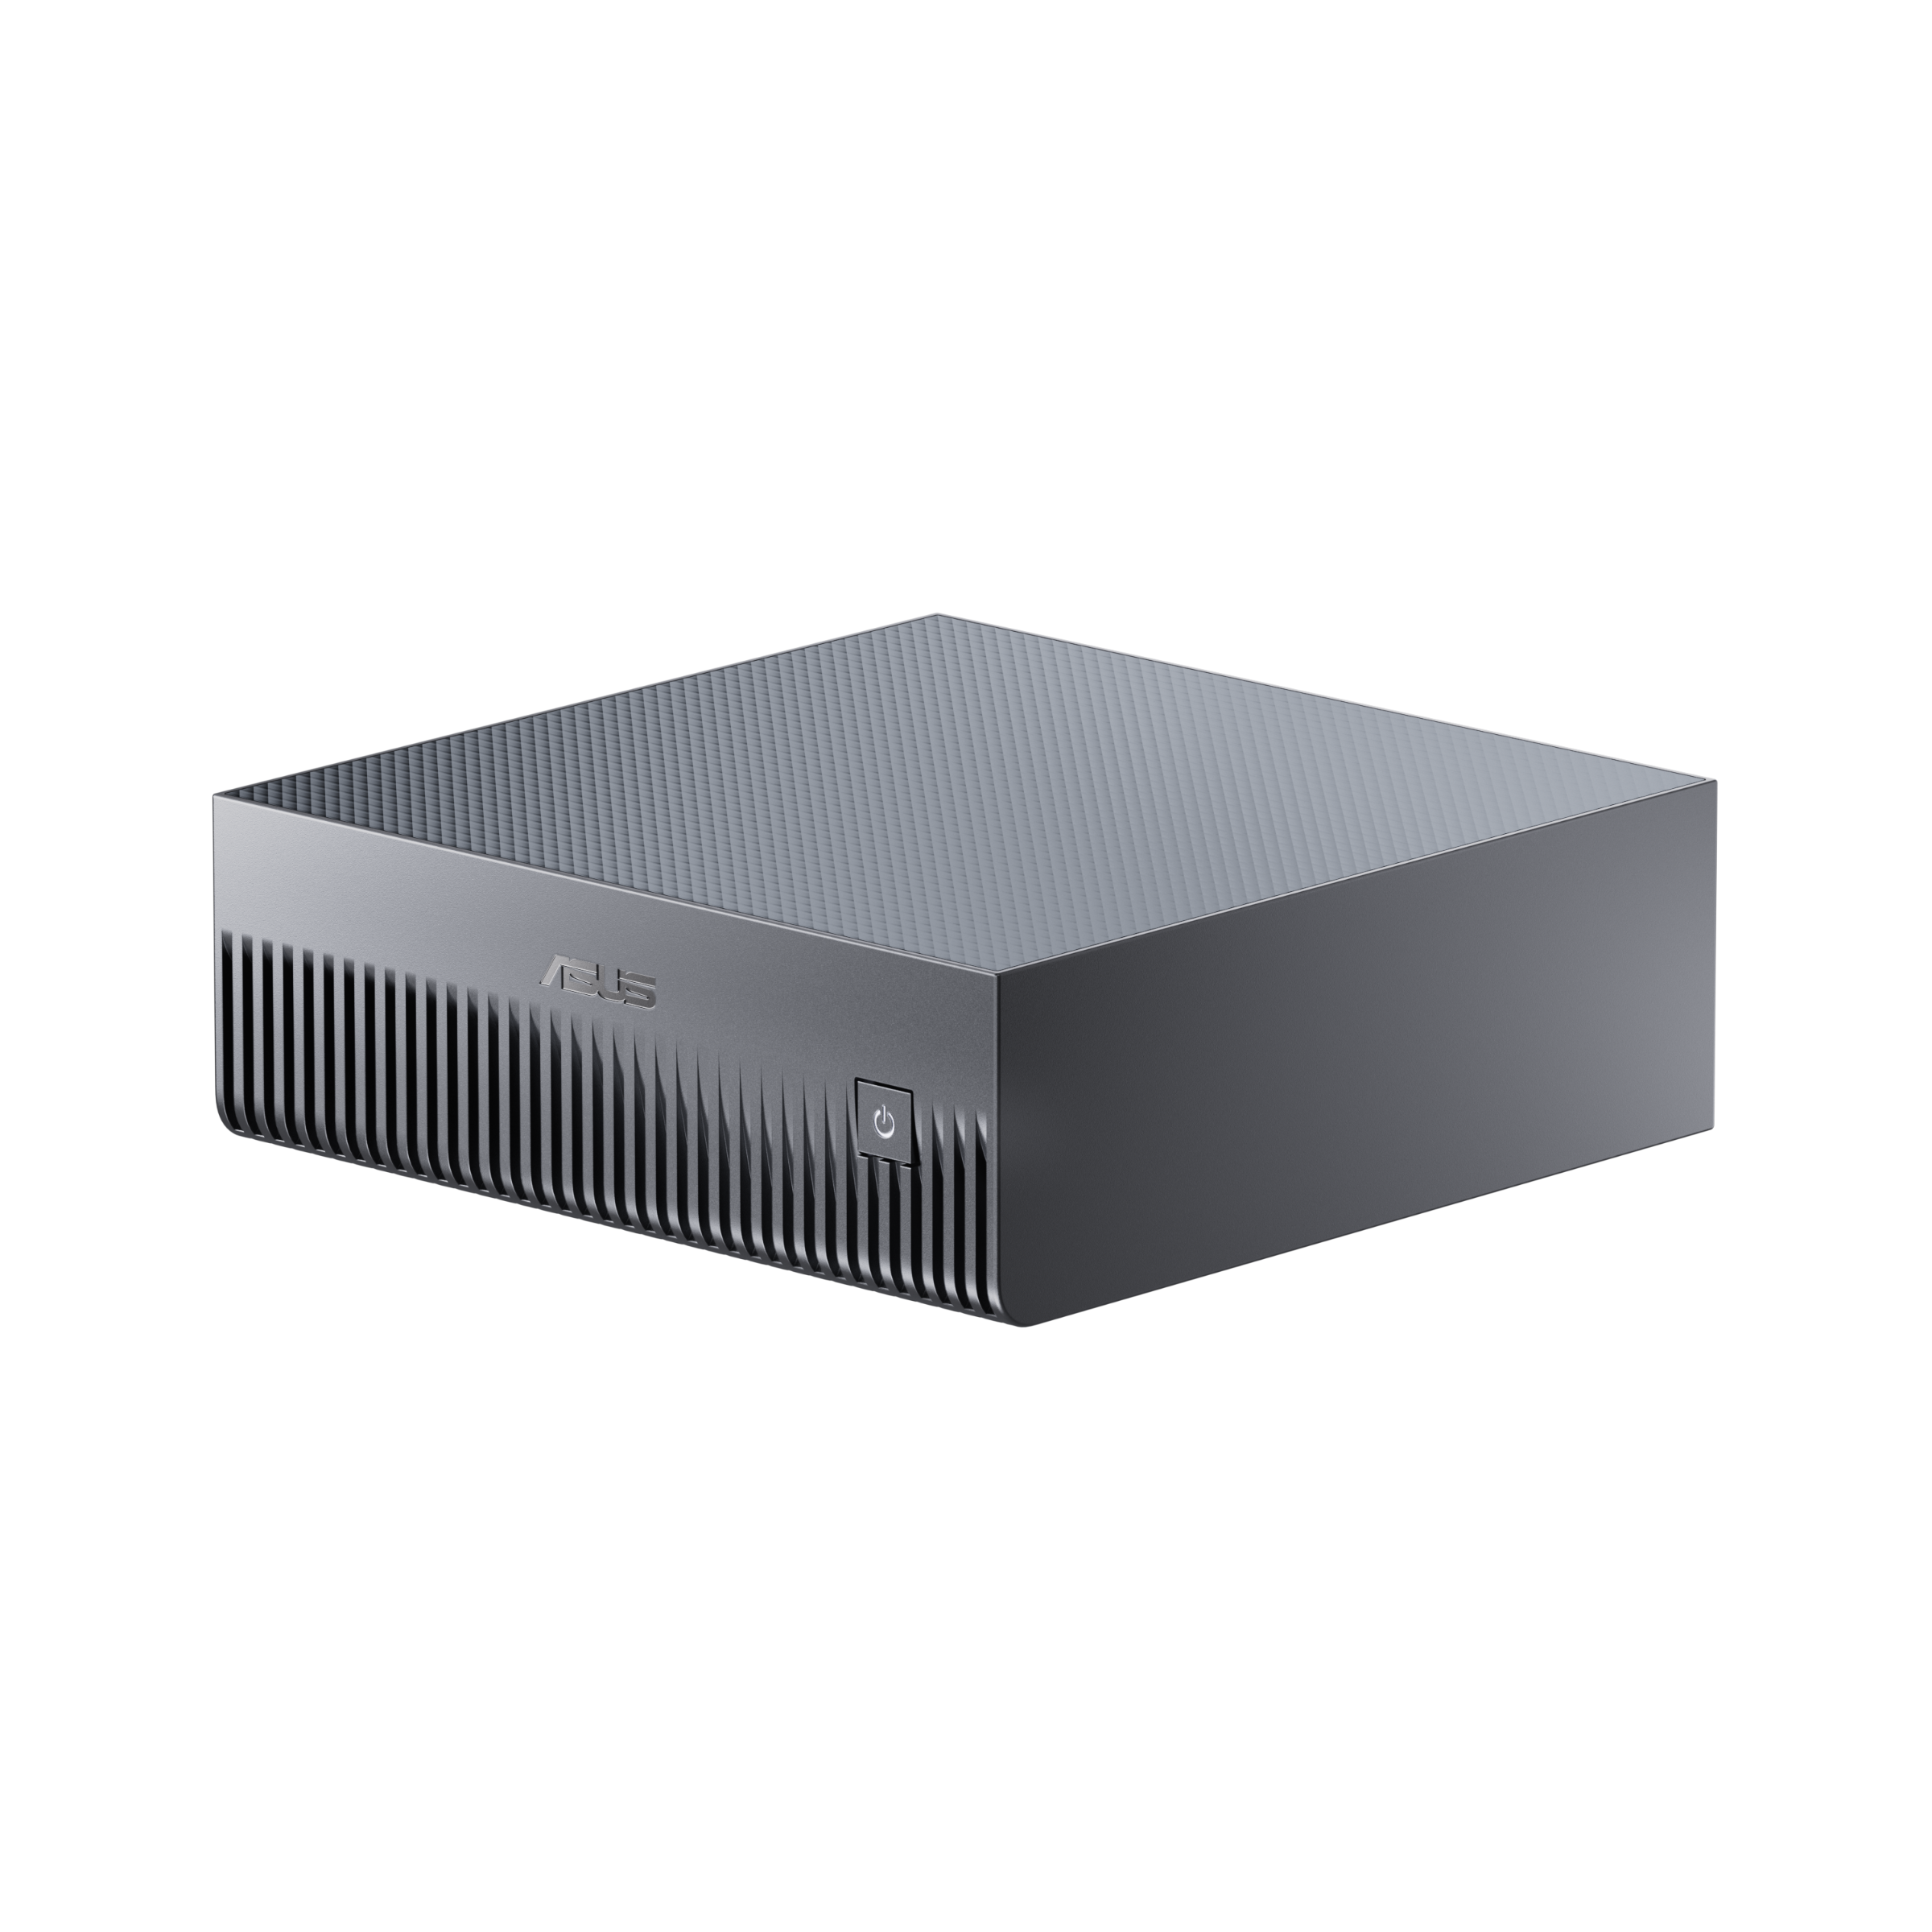
128 GB · LPDDR5x · unified
2 × 128 GB · LPDDR5x · unified
48 GB · GDDR6