Inference in a server environment
Measure service latency and throughput with a realistic request queue.
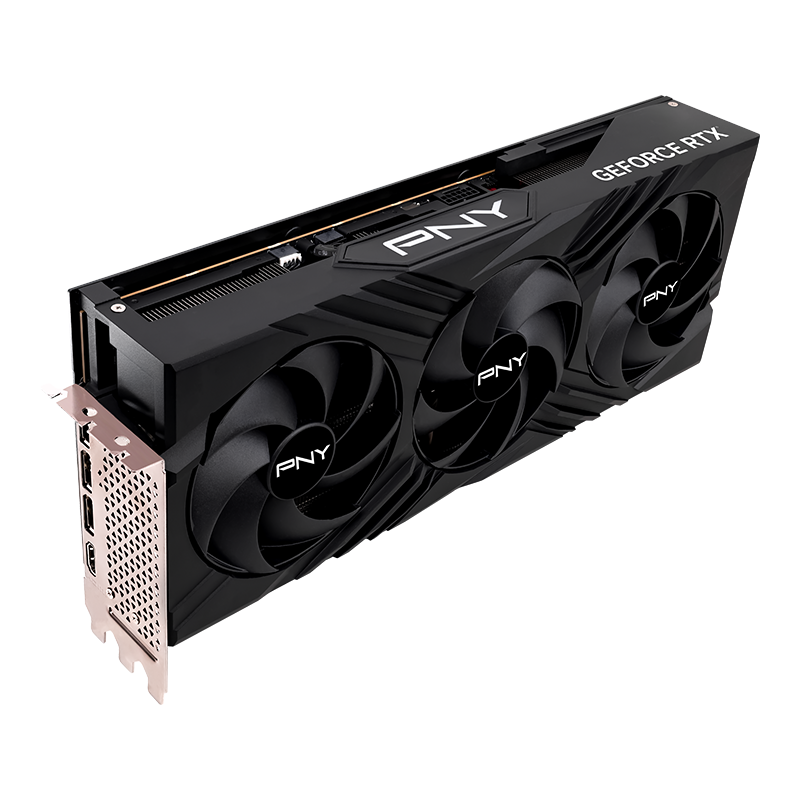
A data center GPU with RT cores for inference, rendering and video workloads.
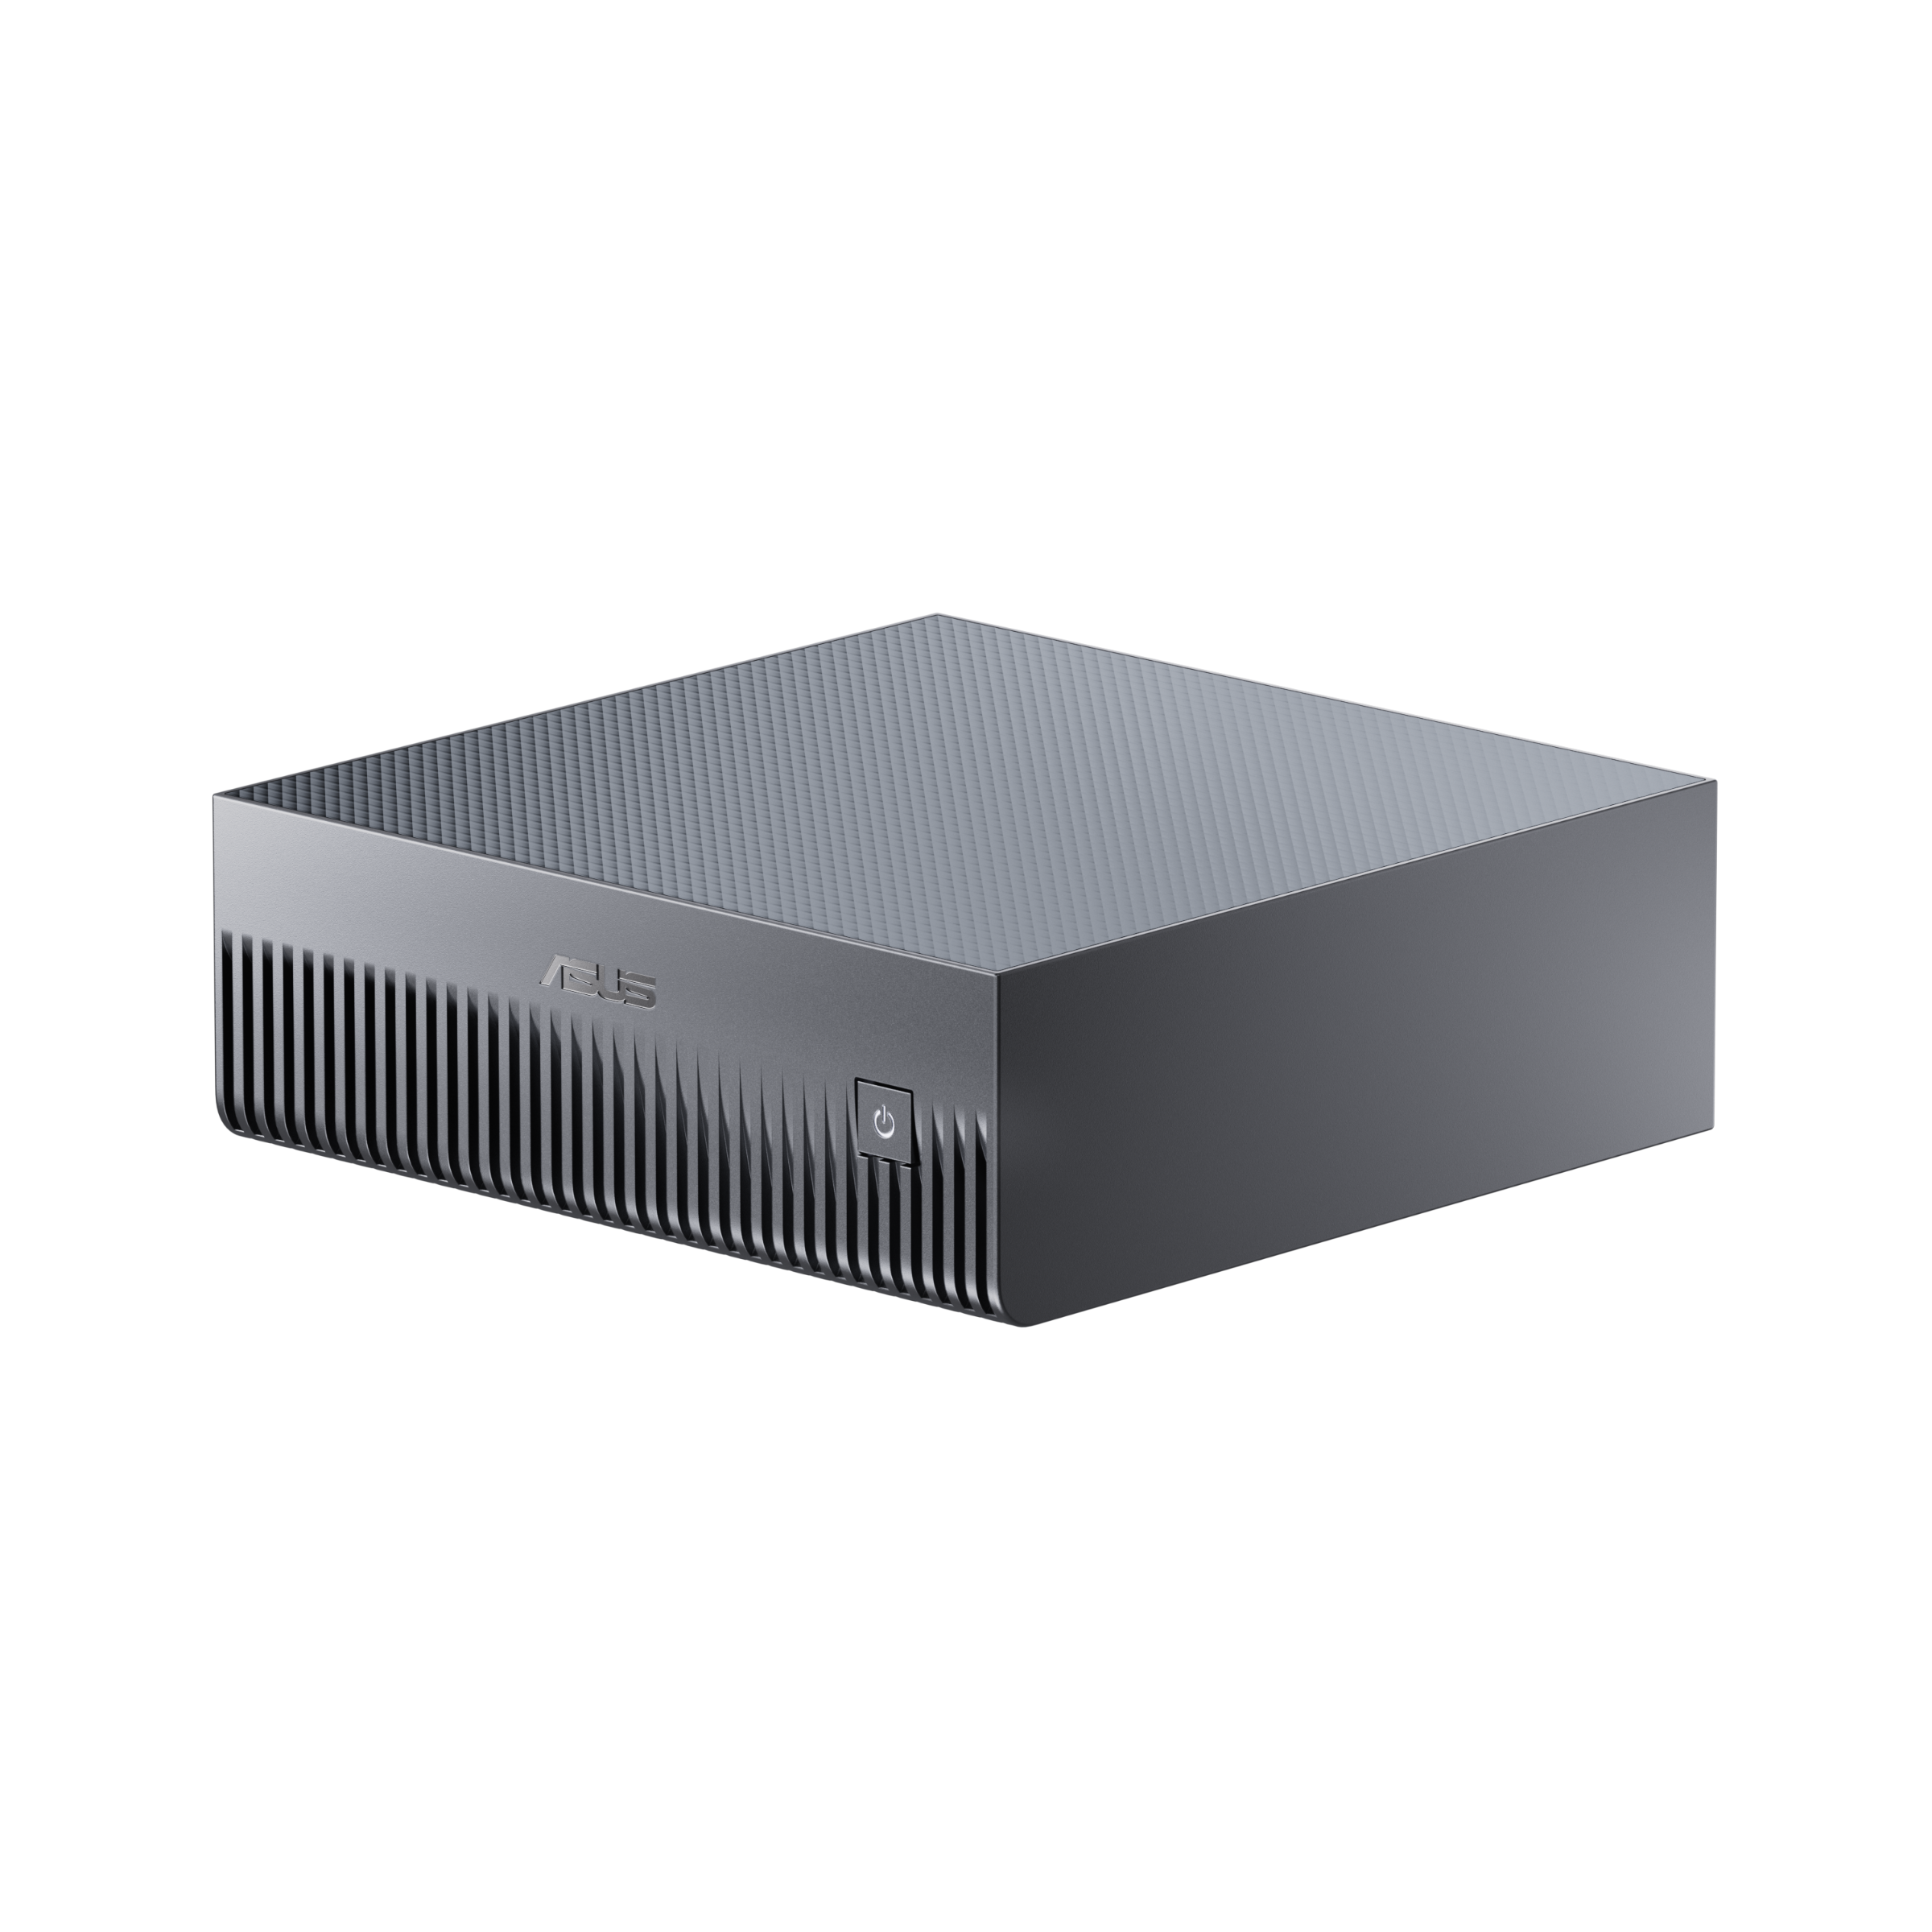
Choosing L40S to run a language model? Compare your workload with ASUS Ascent GX10 rental: NVIDIA GB10 and 128 GB of unified CPU and GPU memory on one node.
Request one ASUS system for inference and RAG, or a pair for parallel workloads. Compare model and context memory, ARM64 support and the time needed for a trial run. GX10 unified memory and dedicated VRAM have different trade-offs.
Match ASUS GX10 to your model128 GB unified memory · NVIDIA GB10 · one system or a pair. Availability and software are agreed for your workload.
Measure service latency and throughput with a realistic request queue.
L40S combines compute capabilities with RT cores for graphics workloads.
Test decoding, AI processing and encoding together as one pipeline.
Provide your model, software environment and rental period. We will confirm the rate, availability and connection method before the rental starts.
The GPU has 48 GB of GDDR6. Include runtime memory and working buffers in the total.
L40S includes Tensor and RT cores as well as video processing engines. To run several stages together, check application support and their combined memory use.
This configuration is open for rental requests. Share your workload, preferred dates and duration. Hardware availability, pricing and access dates are confirmed individually; a request does not create a confirmed booking.