Eight-GPU training
Evaluate scaling with your model, sequence length and batch size.
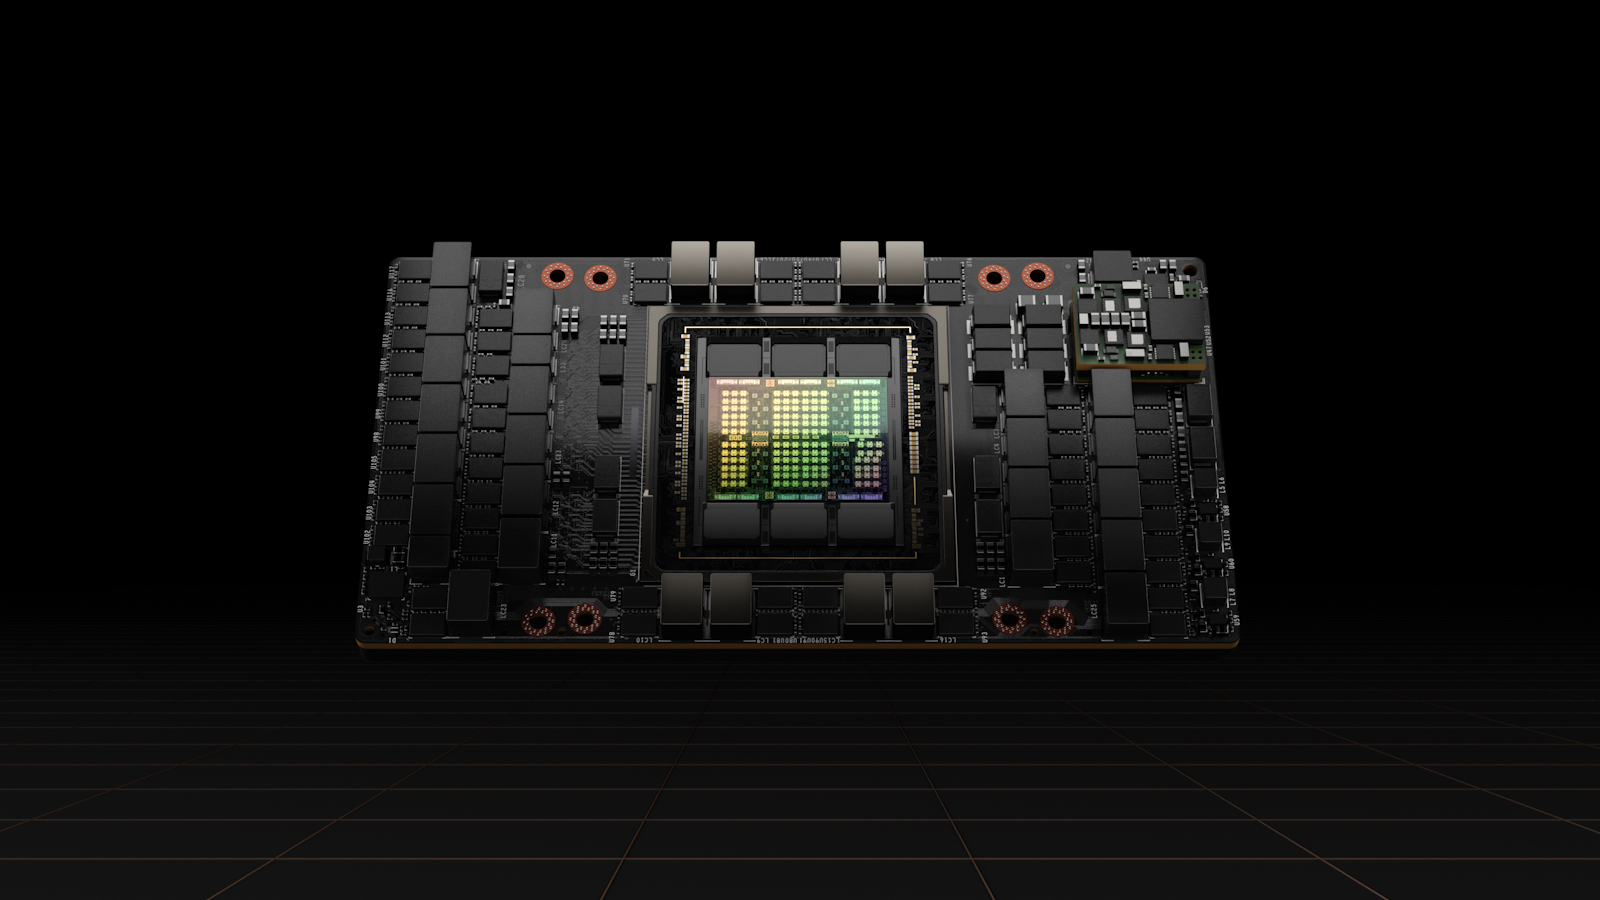
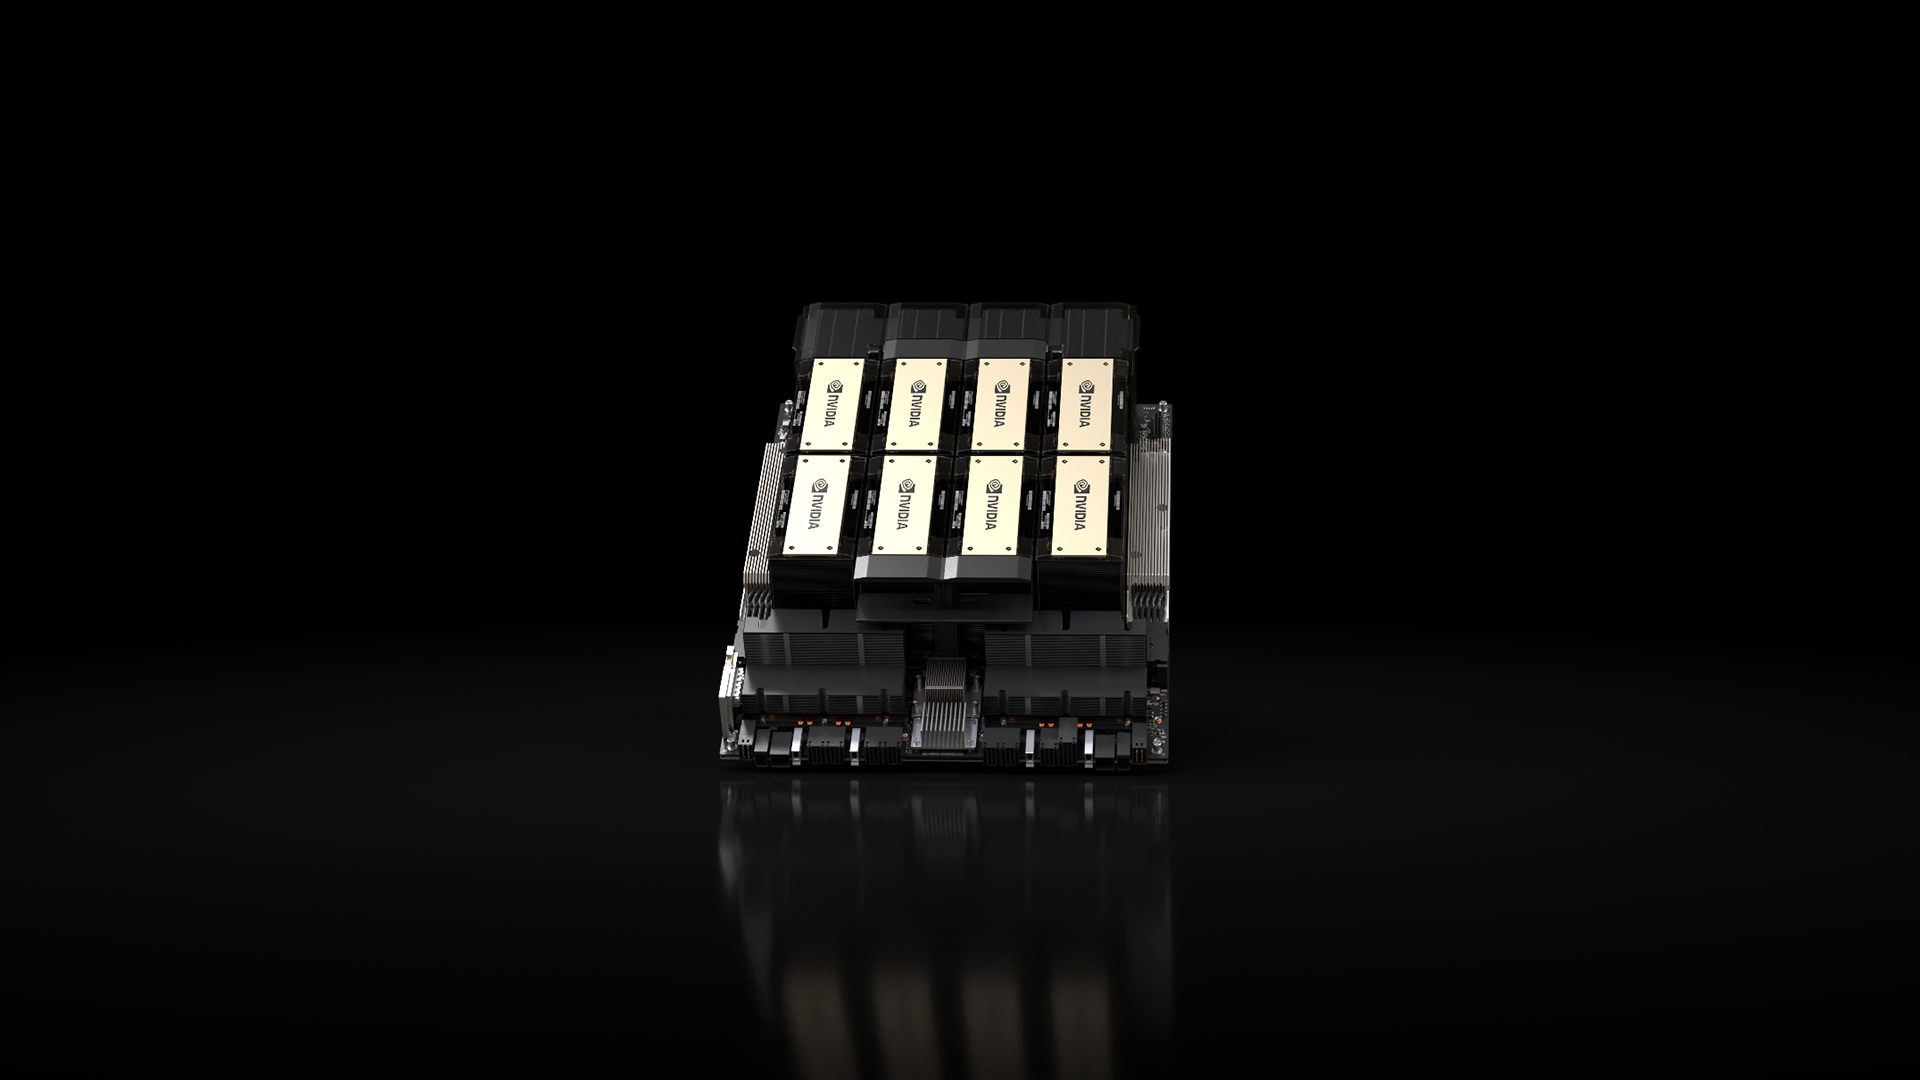
Eight GPUs with 80 GB each for distributed training and inference.
Evaluate scaling with your model, sequence length and batch size.
Choose model sharding around per-GPU memory and interconnect requirements.
Allocate resources across independent experiments with explicit GPU assignment.
Provide your model, software environment and rental period. We will confirm the rate, availability and connection method before the rental starts.
Memory is per card: 8 × 80 GB HBM3. It is not automatically pooled.
Find the smallest device count that fits the model and working data, then compare speed and utilization. More GPUs may not help if data delivery or communication is the bottleneck.
This configuration is open for rental requests. Share your workload, preferred dates and duration. Hardware availability, pricing and access dates are confirmed individually; a request does not create a confirmed booking.