Models with larger weights
Evaluate placing the model on one GPU while allowing for engine memory.
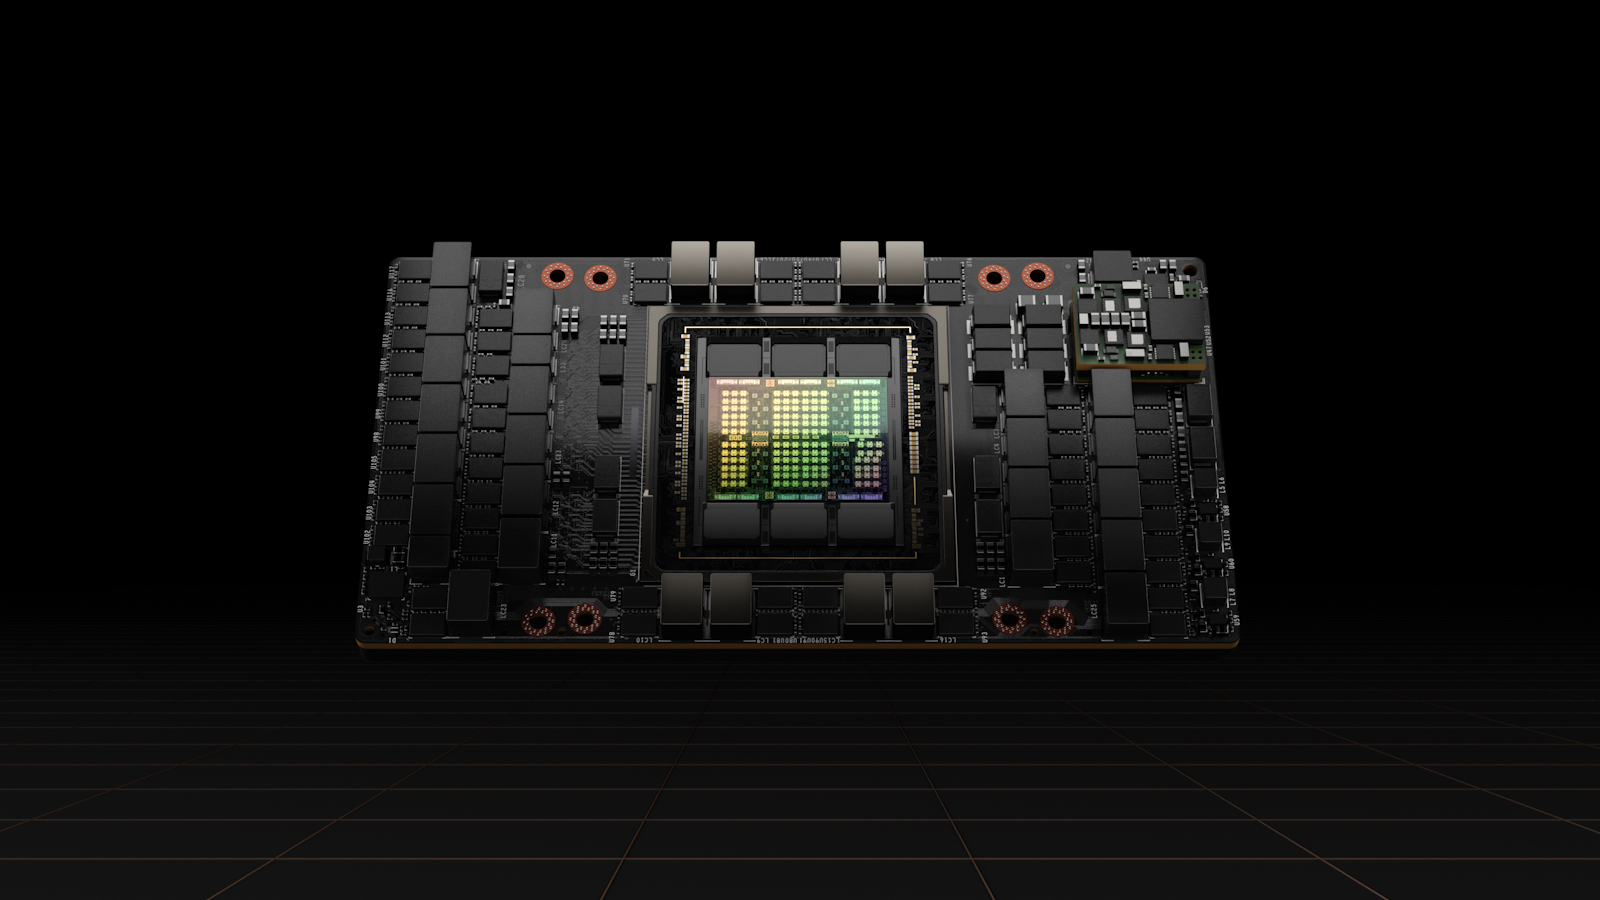
141 GB on one GPU for model weights, KV cache and working buffers.
Evaluate placing the model on one GPU while allowing for engine memory.
Measure KV cache growth at your actual input and output lengths.
Balance request concurrency, latency and the 141 GB memory budget.
Provide your model, software environment and rental period. We will confirm the rate, availability and connection method before the rental starts.
The GPU has 141 GB of HBM3e. Include runtime memory and working buffers in the total.
Additional memory may be needed for KV cache, concurrent requests or training state. Measure peak usage at your target load to understand whether the extra capacity helps.
This configuration is open for rental requests. Share your workload, preferred dates and duration. Hardware availability, pricing and access dates are confirmed individually; a request does not create a confirmed booking.