Two independent experiments
Run separate jobs on each card when each fits within its own 24 GB.
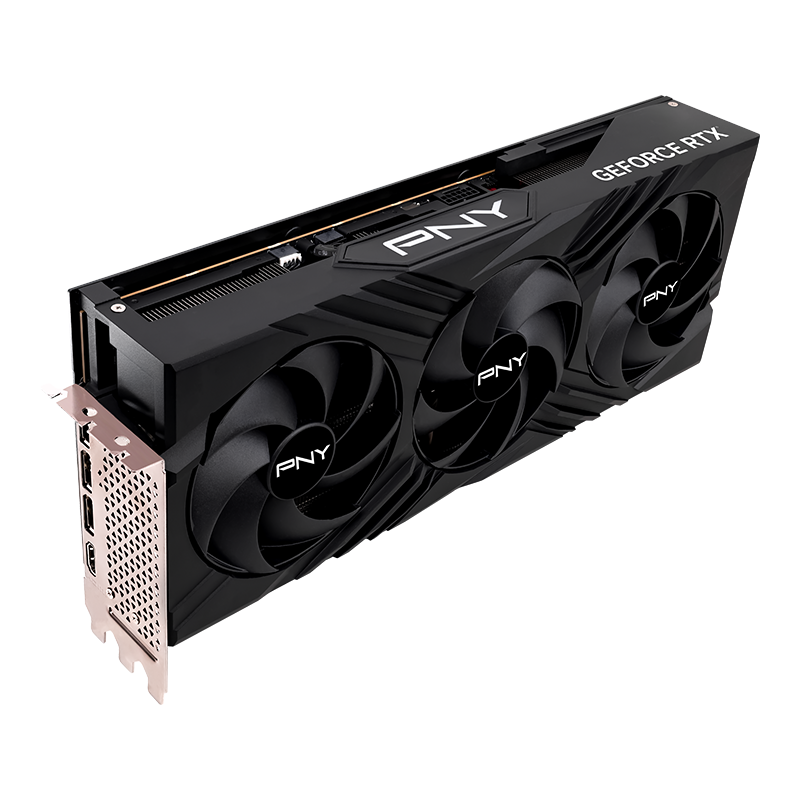
Two cards with 24 GB each for separate workloads or supported multi-GPU runs.
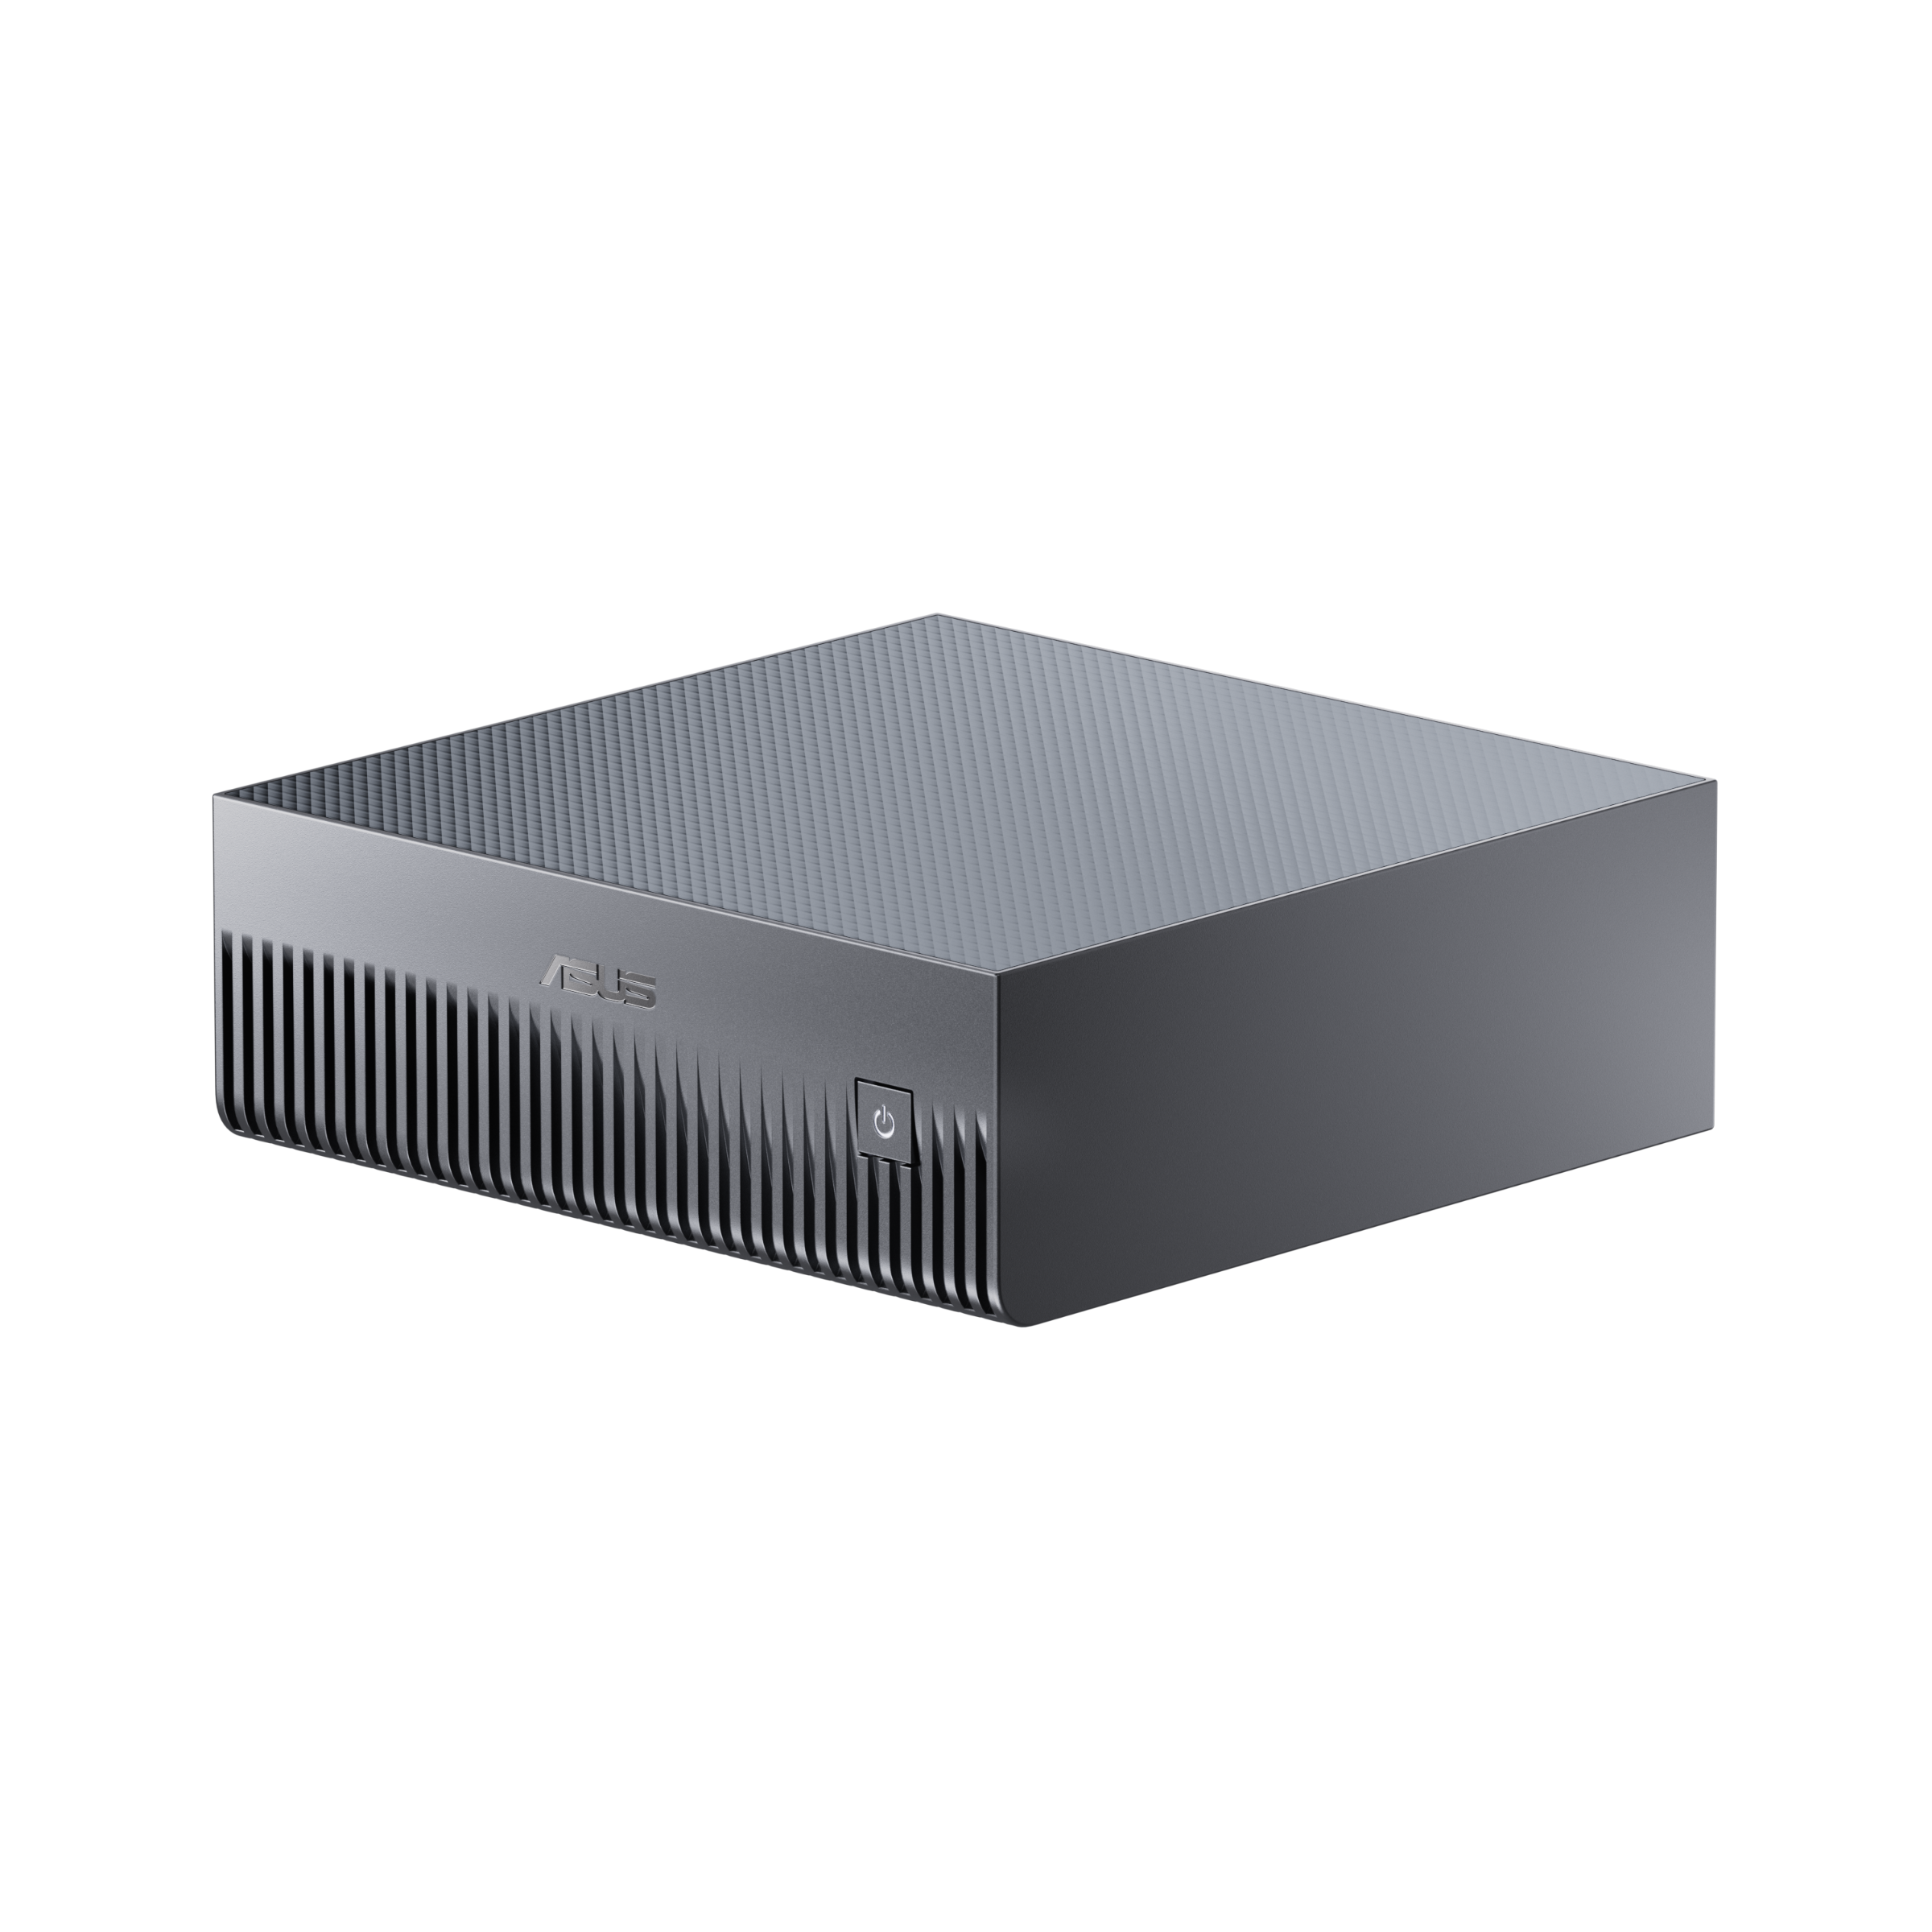
Choosing 2 × RTX 4090 to run a language model? Compare your workload with ASUS Ascent GX10 rental: NVIDIA GB10 and 128 GB of unified CPU and GPU memory on one node.
Request one ASUS system for inference and RAG, or a pair for parallel workloads. Compare model and context memory, ARM64 support and the time needed for a trial run. GX10 unified memory and dedicated VRAM have different trade-offs.
RTX 4090 or ASUS GX10 for LLMs128 GB unified memory · NVIDIA GB10 · one system or a pair. Availability and software are agreed for your workload.
Run separate jobs on each card when each fits within its own 24 GB.
Distribute frames through an engine or queue that supports multiple GPUs.
Test model distribution in your runtime and measure communication overhead.
Provide your model, software environment and rental period. We will confirm the rate, availability and connection method before the rental starts.
Memory is per card: 2 × 24 GB GDDR6X. It is not automatically pooled.
Independent jobs can run on both cards in parallel. For one job, results depend on work distribution and data transfers; linear scaling is not guaranteed.
This configuration is open for rental requests. Share your workload, preferred dates and duration. Hardware availability, pricing and access dates are confirmed individually; a request does not create a confirmed booking.