Training at a defined batch size
Check whether weights, activations and optimizer state fit in 40 GB HBM2.
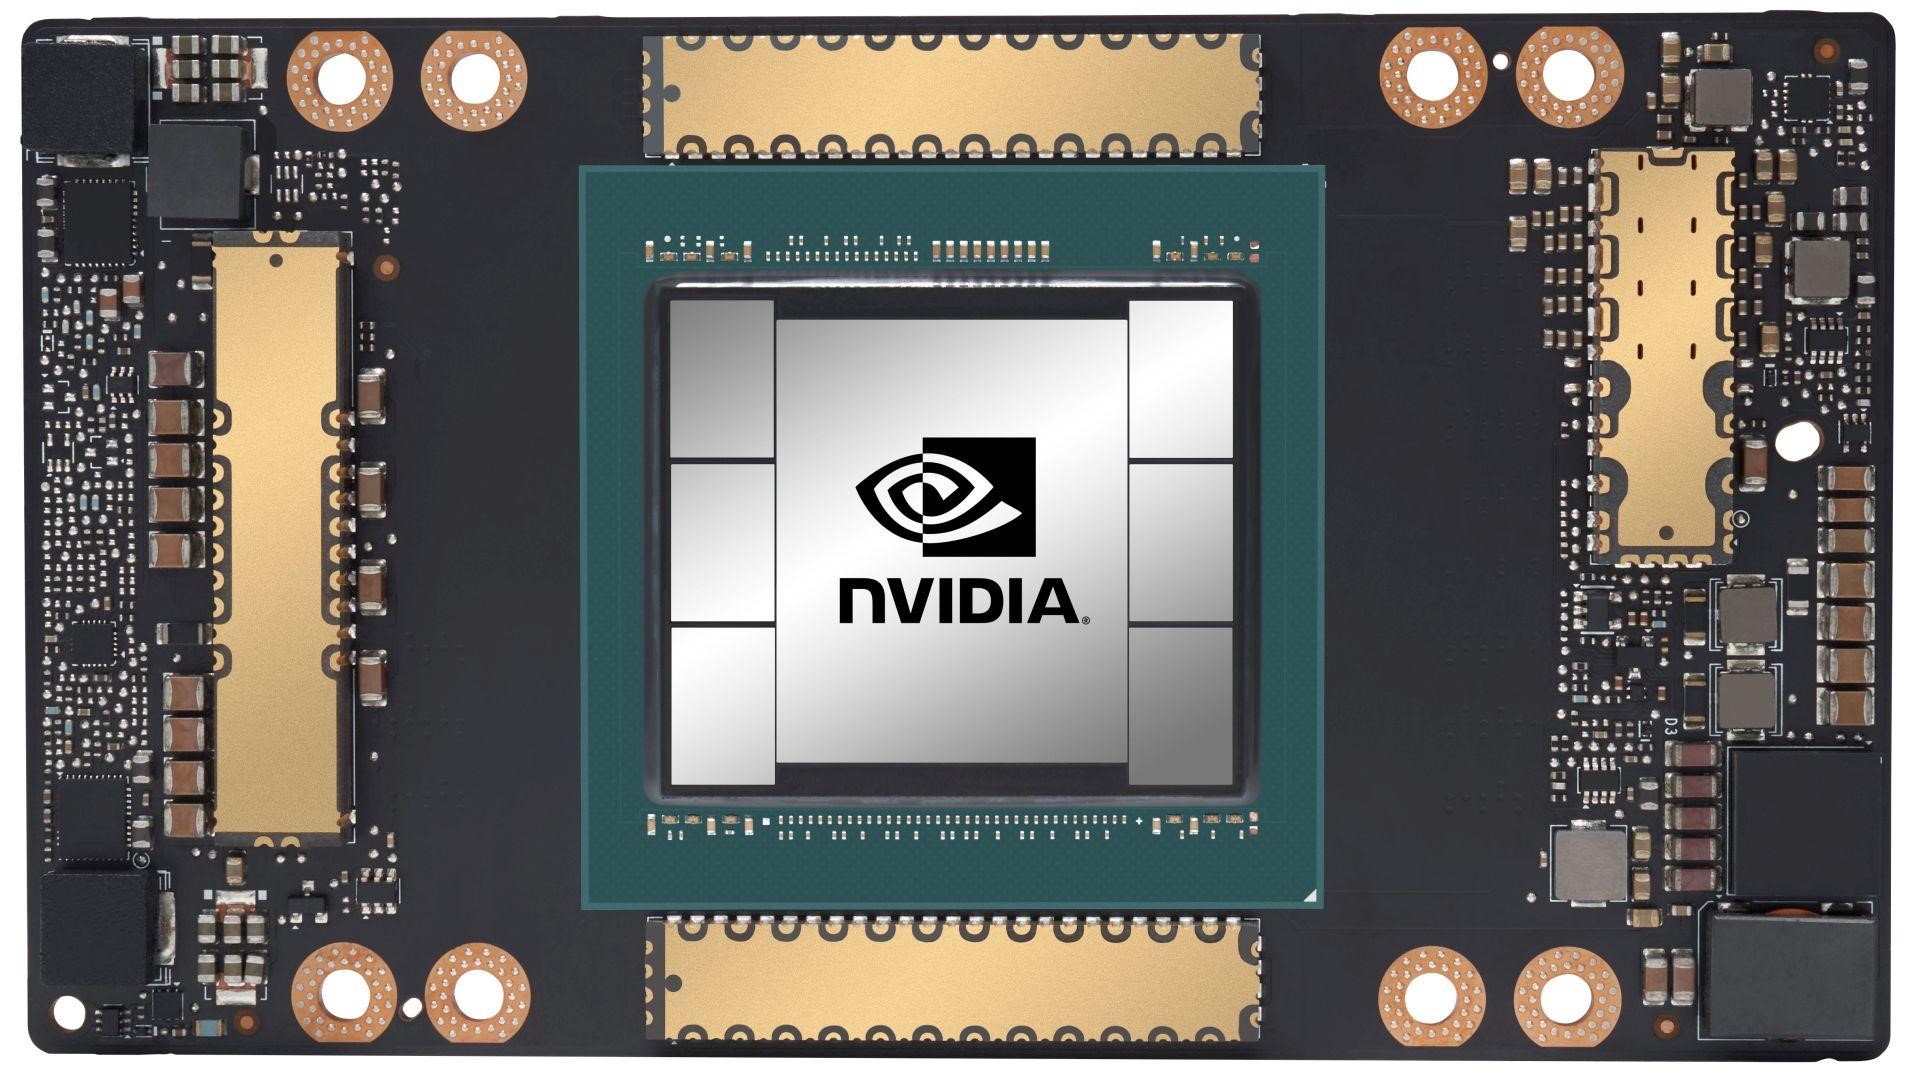
Ampere in the SXM form factor with 40 GB HBM2 for AI and scientific computing.
Check whether weights, activations and optimizer state fit in 40 GB HBM2.
Tune quantization and context length around the actual memory limit.
Test your CUDA application on a representative problem at the required precision.
Provide your model, software environment and rental period. We will confirm the rate, availability and connection method before the rental starts.
The GPU has 40 GB of HBM2. Include runtime memory and working buffers in the total.
Choose 80 GB if model weights, context and working data do not fit in 40 GB, or if you need a longer context or larger batch size. The 80 GB version uses HBM2e. Compare performance on your workload.
This configuration is open for rental requests. Share your workload, preferred dates and duration. Hardware availability, pricing and access dates are confirmed individually; a request does not create a confirmed booking.